Post-Mortem: How a Tiny Counter Froze Our API
Hey everyone!
On Tuesday, September 29th, PDFMonkey was slow for a little under an hour. Creating or deleting a document through the API could take 30 seconds or more, and some of you probably ran into timeouts. We’re sorry about that.
The cause was a small change we made back in May. It passed all our tests and ran without trouble for five months, but the idea behind it was flawed from the start. We’d like to explain what happened, because it’s an easy mistake to make.
TL;DR
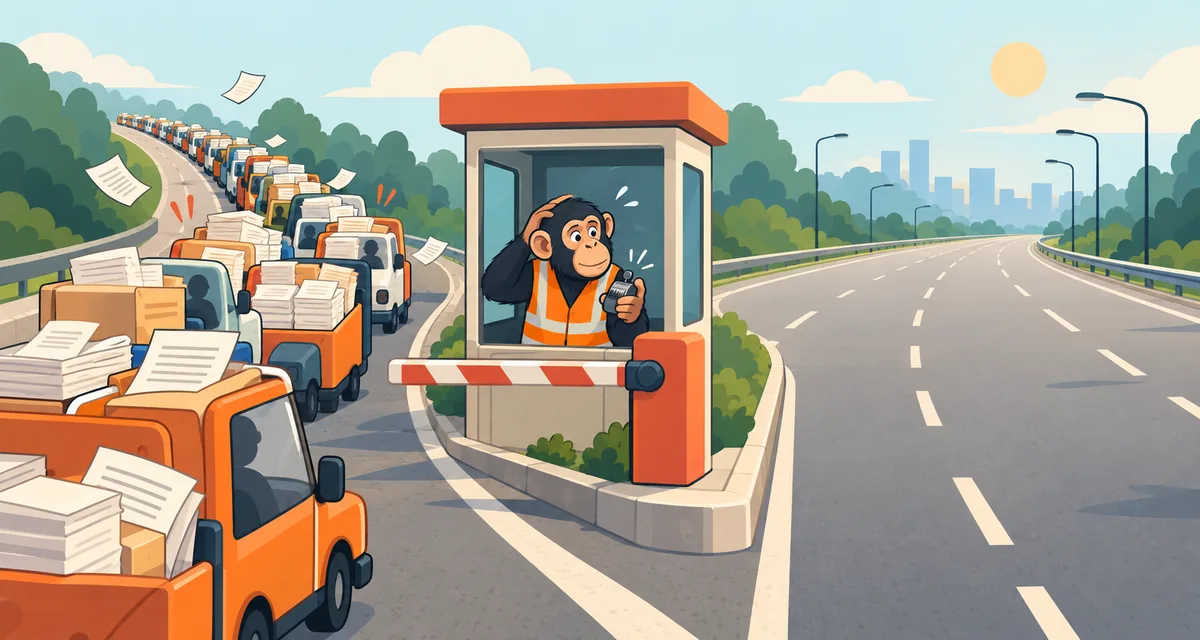
- To keep track of how many documents each workspace has, a database trigger updated the same row every time a document was created or deleted.
- As a result, the documents of a given workspace could only be written one at a time. When a large workspace sent a big batch, more than a hundred database connections ended up waiting in line.
- We turned the trigger off to get things moving again, then rebuilt the counter a different way.
The counter
We needed to know how many documents each workspace has, and we needed that number quickly. Some workspaces have almost two million documents, so counting them every time wasn’t an option.
In May, we added a live_documents_count column to the workspaces table, and a Postgres trigger to keep it up to date:
CREATE TRIGGER documents_sync_workspaces_live_documents_count
AFTER INSERT OR UPDATE OR DELETE ON documents
FOR EACH ROW EXECUTE FUNCTION sync_workspaces_live_documents_count();

-- …which, for every new document, runs:
UPDATE workspaces SET live_documents_count = live_documents_count + 1
WHERE id = NEW.workspace_id;
We liked this approach. A trigger runs no matter how the data changes: through our app, a bulk update or a manual SQL query. Our tests covered all of those cases and the count was always right.
What went wrong
When Postgres updates a row, it locks that row until the transaction is committed. Any other transaction that wants to update the same row has to wait.
Because of the trigger, every new document in a workspace updated the same workspaces row. Two documents created at the same time for the same workspace couldn’t be saved in parallel anymore: the second one had to wait for the first.
Most of the time, nobody noticed. A typical workspace creates a few documents a minute, the lock only lasts a few milliseconds, and nobody waits.
On September 29th, one of our largest customers sent a big batch of document creations and deletions. When we looked at the database, we found 114 connections waiting on a lock, all for documents of that same workspace. One of them was holding the lock for several seconds and blocking 81 others on its own.
That’s what turned a slowdown into an incident. Our document creation transaction stays open while the app does other work, sometimes for a few seconds. With a lock held that long, the line kept growing until it took up the database connections the rest of the API needed.
If you ever have to investigate something similar, this is the query that showed us the problem:
SELECT pid, state, wait_event,
       now() - xact_start AS xact_age,
       cardinality(pg_blocking_pids(pid)) AS blocked_by,
       left(query, 80) AS query
FROM pg_stat_activity
WHERE state <> 'idle'
ORDER BY xact_start;
We disabled the trigger and things went back to normal right away. We’ve since rebuilt the counter so that saving a document no longer updates a shared row.
What we learned
A counter updated by every write becomes a bottleneck. Keeping a running total looks like a way to make reads faster, but it means every write goes through the same row. That’s fine with little traffic, much less so for anything a customer can do in bulk.
We tested that it was correct, not that it held up under load. Our tests checked the count after each kind of change, but never ran two changes at the same time. Our staging environment never sees traffic like this either.
Long transactions make locks much worse. A lock held for a few milliseconds goes unnoticed. Held for a few seconds, it becomes a problem.
Not every number needs to be exact in real time. This count could have been a few seconds behind without anyone noticing, and it would have been much cheaper.
Thanks for your patience, and sorry again if you were affected. If you have questions or noticed anything odd that day, don’t hesitate to reach out.
The PDFMonkey Team 🐒
Simon is passionate about development, tech, design and continuous enhancement. CTO and Co-Founder at PDFMonkey he supervises the development and evolution of the platform making sure the product always respects our core values.